I changed one llama.cpp flag, and my 8GB laptop GPU now runs a 35B model faster than I can read
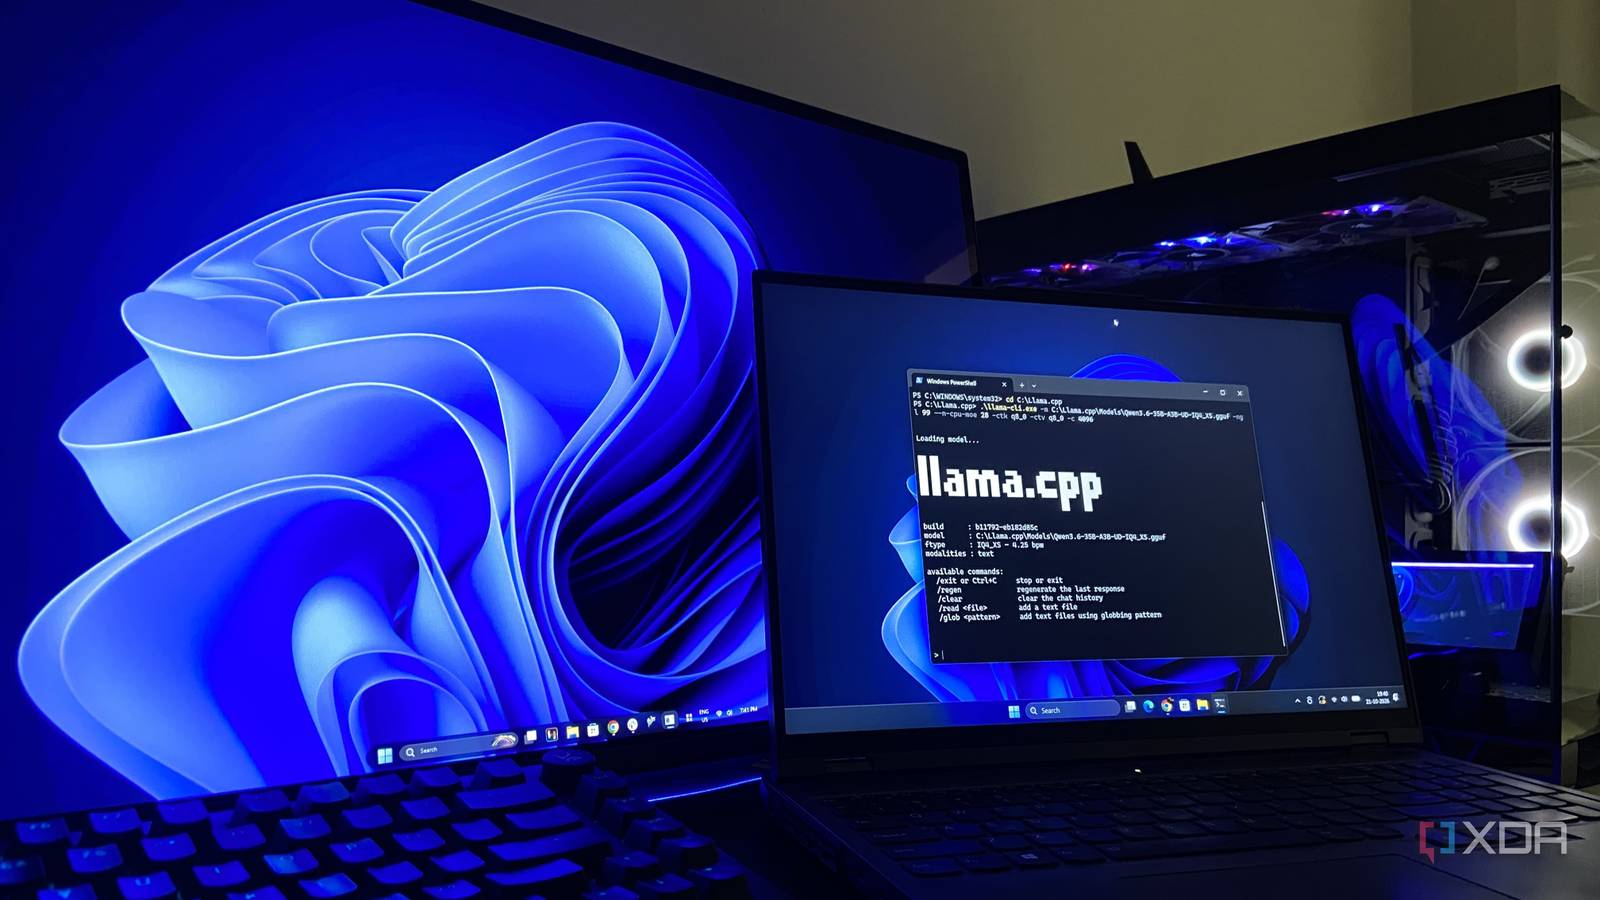
8GB of VRAM isn't the bottleneck, your settings probably are
This is a summary aggregated from XDA Developers. Read the complete article on the original site:
Read full article at XDA Developers