
I moved my local models from Ollama to llama.cpp, and the reason I stayed has nothing to do with speed
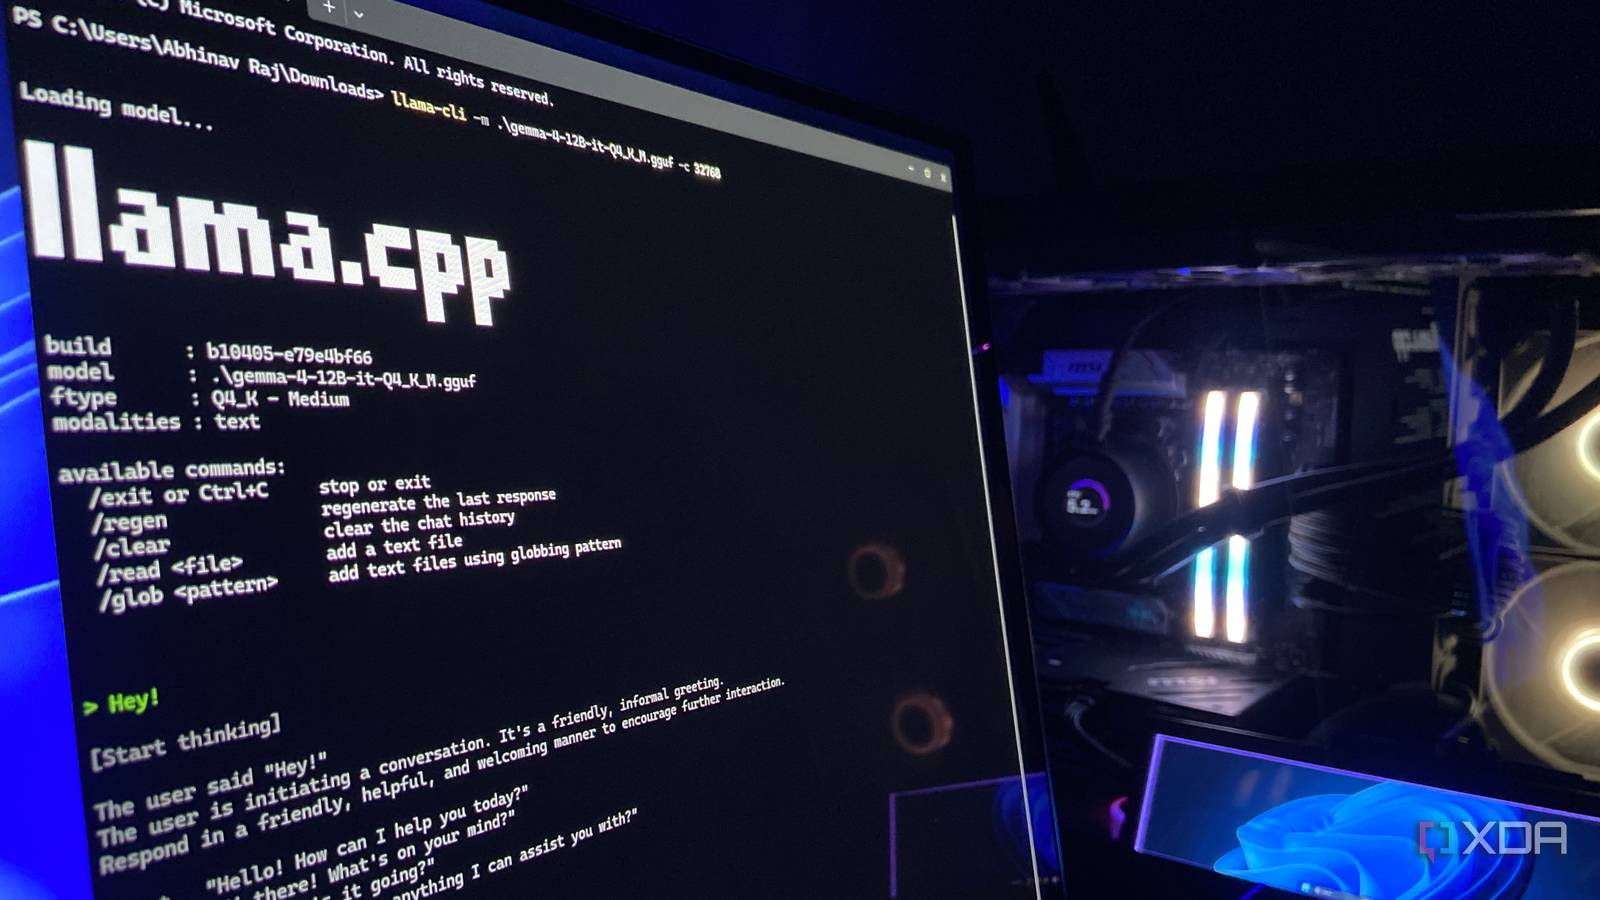
Convenience beats tokens generated per second, always
This is a summary aggregated from XDA Developers. Read the complete article on the original site:
Read full article at XDA Developers


